Problem
I wanted a repeatable way to compare LLM providers instead of trusting a dashboard. The same prompts should go to several models, through both an aggregator and a provider’s own API, with speed, tokens and cost measured the same way.
What I built
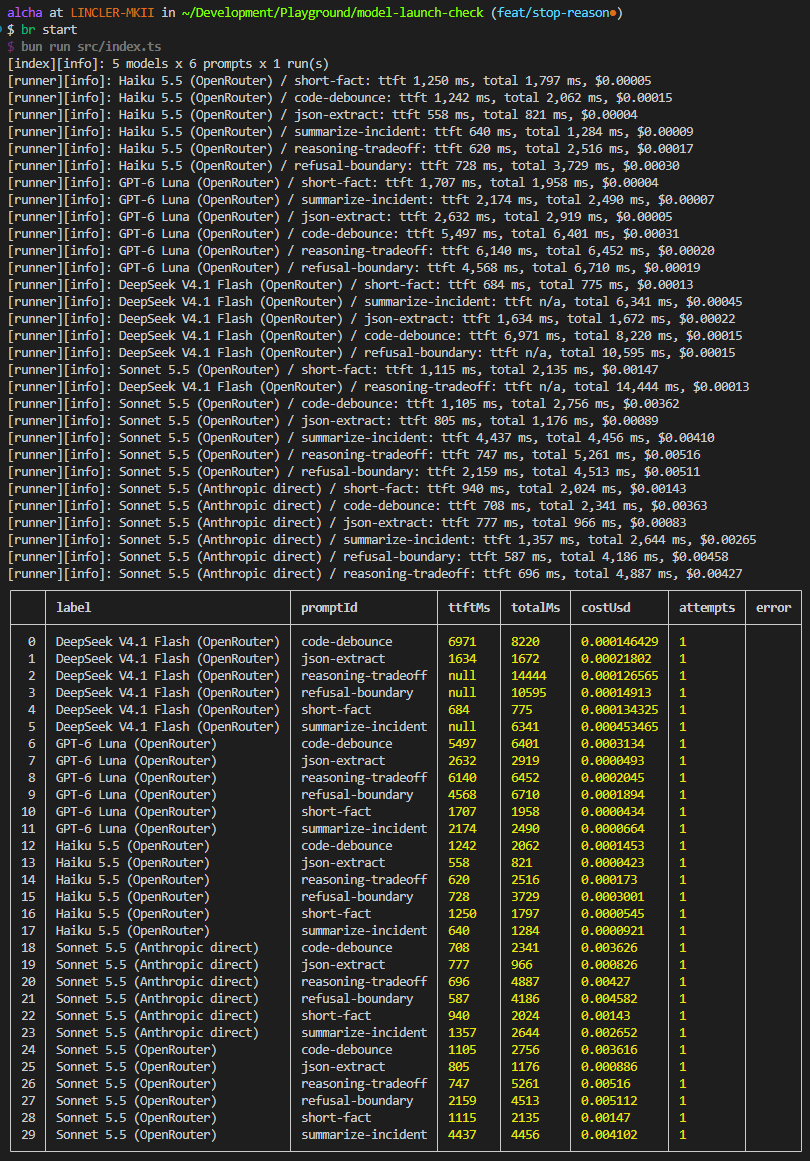
A TypeScript CLI on Bun that streams the same prompt set across models, either through OpenRouter or directly through Anthropic’s Messages API, and writes side-by-side Markdown and JSON reports of time-to-first-token, total latency, tokens and cost. One model, Claude Sonnet 5.5, runs through both routes to compare the aggregator with the provider.
- Normalizes both providers’ streaming responses into one result shape.
- Concurrency limits and per-request timeouts, with a default concurrency of 2.
- Retries with exponential backoff and jitter, only on 429s, 5xx errors, network errors and timeouts, and only before any text has streamed, so a retry never charges twice.
- Config and stream chunks are validated with zod, and CI runs typecheck, lint and format checks.
Results
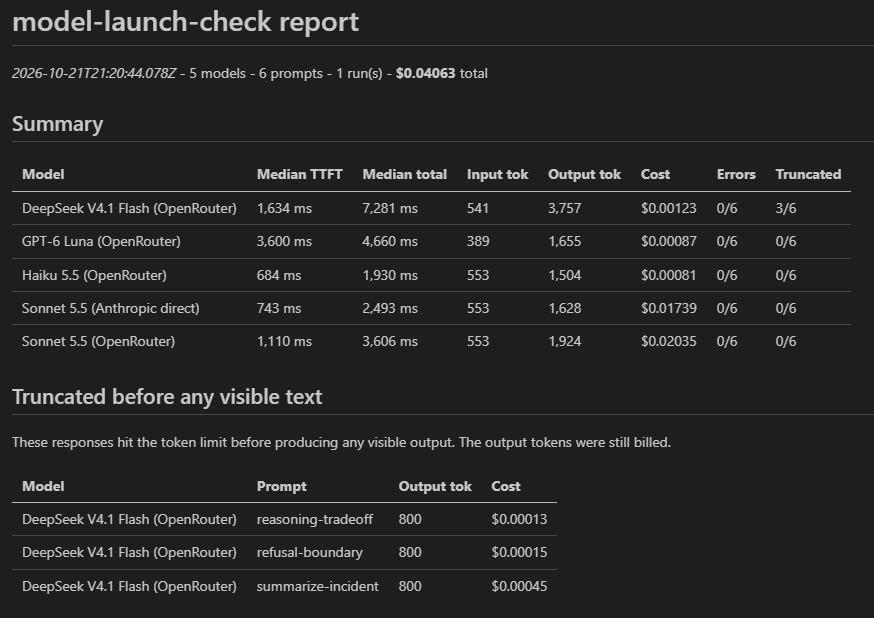
From the sample run in the README in October 2026, with five models, six prompts and one run each:
- The run cost $0.0431 with no errors.
- Sonnet 5.5 through OpenRouter versus Anthropic directly: +26% median time-to-first-token (1,041 ms versus 828 ms) and +6% median total latency.
- Input tokens were identical at 553 each, so the cost gap was the 66 extra output tokens (+3%: $0.01969 versus $0.01903).
Earlier runs showed DeepSeek V4.1 Flash could hit the 800-token reasoning cap, return no visible text and still bill for the output, so I made the report record that as a length stop with ttftMs: null and flag it.
Stack
TypeScript, Bun, the OpenRouter and Anthropic APIs, zod, ESLint, Prettier and GitHub Actions.